Problem
Teams can see that a run was expensive or failed but still spend hours joining cost, calls, retries, and application logs.
Part of Agent FinOps (built as the Agent Lens service)
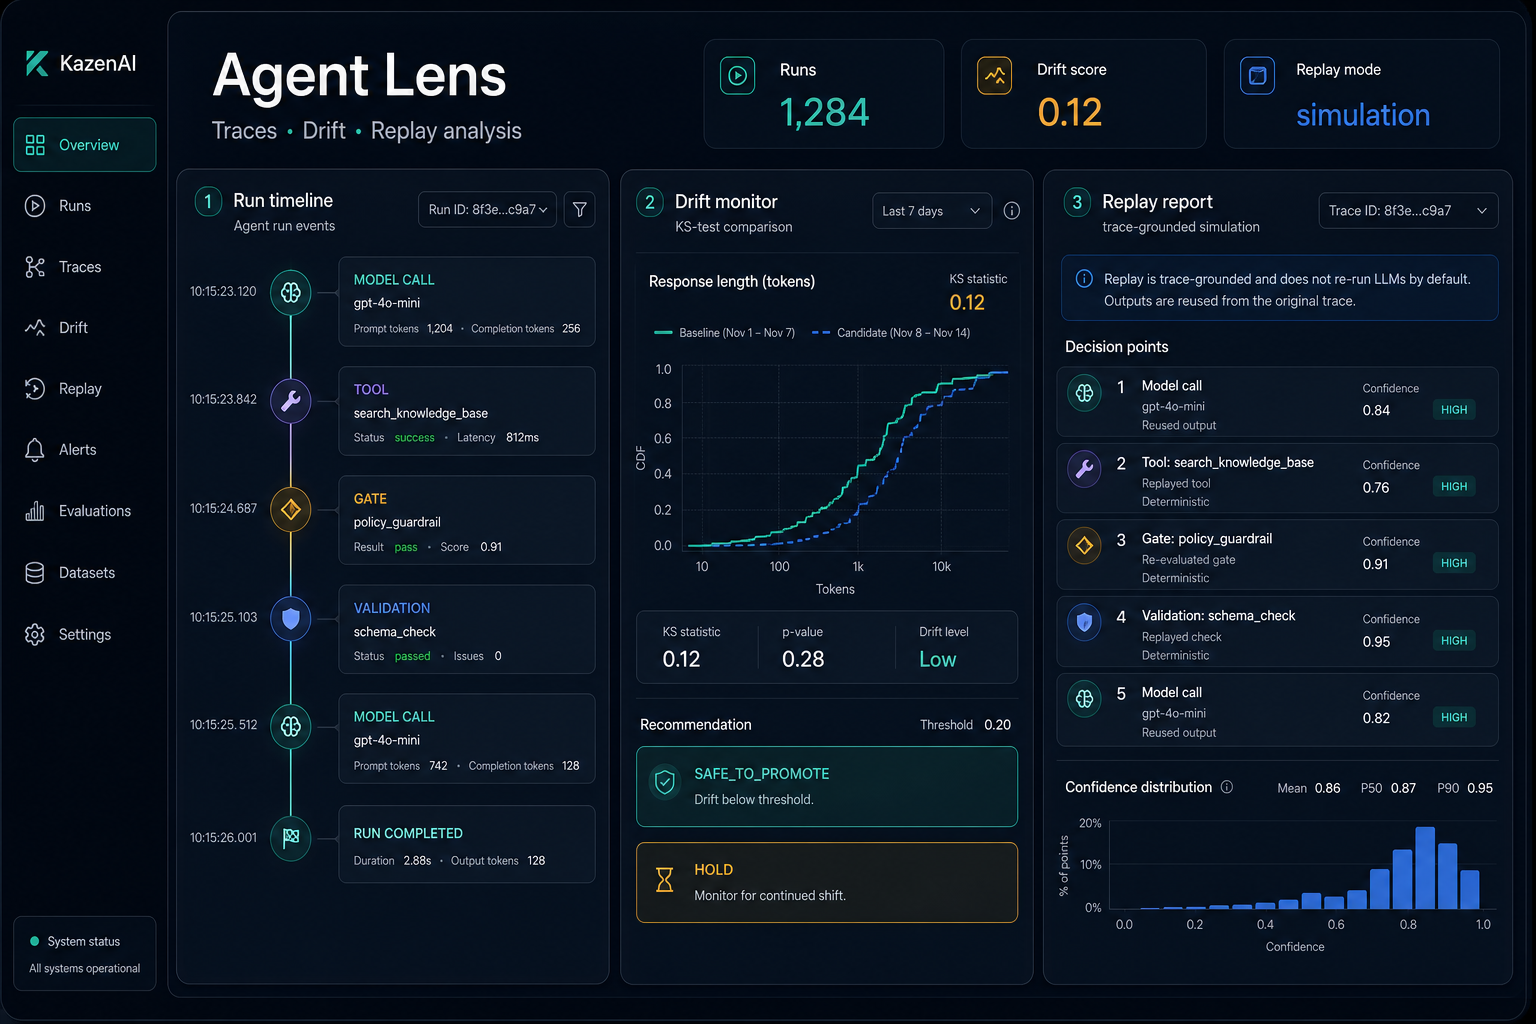
Investigate the calls, retries, cost, and policy evidence behind an expensive or failed run.
A cost alert or failed result rarely explains the sequence that produced it. Teams may have provider logs, application logs, and traces, yet still join them manually during an incident.
Run receipts connect the FinOps decision to readable run history and incident evidence so the owner can review what happened without pretending that an existing-run comparison proves causality.
Work with me:
Teams can see that a run was expensive or failed but still spend hours joining cost, calls, retries, and application logs.
Run timelines and incident records use the same run context as Agent FinOps, with review history and bounded comparison of existing captured runs.
The technical owner can move from an alert to the relevant costly step, retry, or policy decision and record a reviewable conclusion.
Incident workflows are locally integration-verified with synthetic data. Customer production use requires separate verification.
Bring one expensive or failed workflow and the investigation gap you want to close.
Send a problem briefIllustrative incident evidence from a captured run.
workflow:          report_generation
run_id:            run_01J...
incident:          repeated_model_retry
occurrences:       4
cost_state:        settled
review_status:     needs_review
comparison:        existing_runs_only
Current boundary: Existing-run comparison is evidence, not causal proof or an automatic fix. Hosted evidence uses sample data; customer production deployment requires separate verification.
Make costly and failed agent behavior inspectable from the evidence already captured. Timelines operators can read, recurring incidents they can review, and explicit limits on what the evidence proves.
Run receipts separate what the captured evidence shows from what still requires an engineering investigation. A comparison can expose a difference without proving that the difference caused the outcome.
I built run receipts (the Agent Lens service) as the explanatory half of Agent FinOps: connect the cost and spending decision to the calls, retries, and incident record behind the run.
Agent systems become operable when a team can explain a costly or failed execution without manually stitching together every provider and application record. That is the Phase I KazenAI product hypothesis.