Problem
A portfolio assistant can invent, stall, or become expensive without grounding, streaming, and abuse controls.
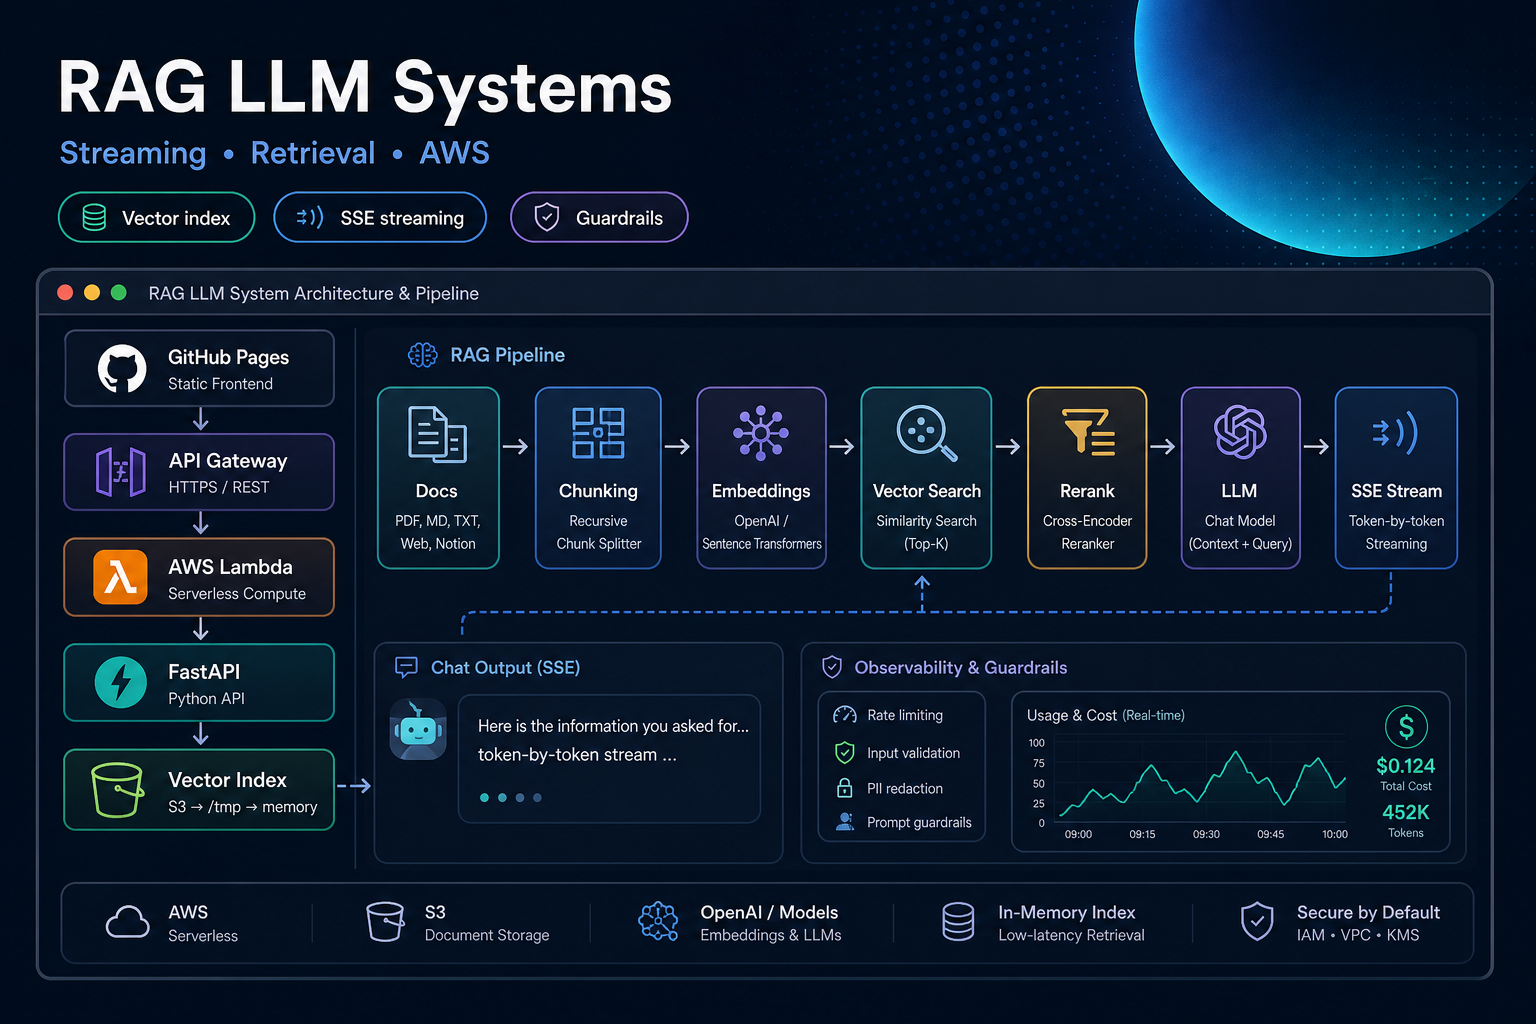
Production-style RAG assistant: retrieval, streaming SSE responses, rate limiting, cost guardrails, and cloud deployment.
This project is a production-style Retrieval Augmented Generation (RAG) system that answers questions about Dhavan Shah (portfolio, experience, Kaggle achievements, and projects). The focus is not just model output quality, but end-to-end AI systems engineering: retrieval, streaming responses, deployment architecture, cost controls, and operational maturity.
Dhavan's Assistant: you can test the grounded assistant at:
A portfolio assistant can invent, stall, or become expensive without grounding, streaming, and abuse controls.
Document ingestion, embeddings, hybrid BM25/vector fusion (RRF), fail-closed commercial facts, LLM synthesis with sentence-level verification, SSE streaming, and edge/app abuse controls work as one pipeline.
RAG quality depends on production behavior too: latency, citations, rate limits, observability, and cost control.
Useful for teams replacing demo chatbots with grounded assistants that need answer discipline and operating limits.
Use this pattern to review grounding, streaming, and cost controls in an assistant workflow.
Send a problem briefBuild a public, portfolio-grade AI assistant that demonstrates real-world engineering around LLM applications: LLM pipelines, vector retrieval, streaming SSE, cloud deployment, rate limiting, cost-aware guardrails, API design, and CI/CD + infrastructure-as-code.
Request/response flow:
RESPONSE_STREAM for SSEsearching → progress? → thinking? → token* → final or errorPOST /v1/query-stream: SSE streaming endpoint (public via edge only).GET /v1/health: readiness (index loaded).GET /v1/metrics: sanitized public metrics (no spend detail).
The system follows RAG with an explicit product contract: retrieve published evidence first, generate once, then verify protected claims before committing final.answer.
vector_index.npy, documents.json, facts.json as one validated snapshot.final.answer is authoritative; drafts are provisional.
Responses use Server-Sent Events. Token frames are append-only drafts shown as provisional Thought text.
Only final.answer is committed to the assistant bubble. Event names are
searching, optional progress/thinking, token, then final or error
— not generic chunk/done aliases.
Structured failure metrics (rate limit, budget, bundle, provider, etc.) and Lambda alarms publish to CloudWatch/SNS. Visitor prompt text is not written into metric dimensions; accepted Q&A may be retained ~30 days for debugging.
https://api.dhavanshah.com.This is an AI systems engineering project, not just a model demo. It demonstrates the practical building blocks needed for modern LLM products: grounded retrieval, streaming UX, cost controls, cloud-native deployment, and operational readiness.